To train a chatbot on your own data in LoopReply, open the intended AI Agent, add sources in Knowledge, wait for processing, and test answers against the original material. Documents and website pages provide reference text. Supported CSV, XLSX, and database imports also keep structured rows for exact lookups and calculations.
This is knowledge-base setup using retrieval-augmented generation, or RAG. It does not retrain the underlying language model. An uploaded file is only useful once it is processed, available to the right Agent, and included in the workflow's knowledge sources.
Reviewed October 4, 2026: The steps below reflect the current interface and import limits. Keep the product reference handy for supported behavior and technical limits.
How custom-data answers work
For a question about a policy or product description, the Agent can search relevant passages from its processed knowledge and use them when composing a reply. This gives it business-specific context, but does not guarantee a correct answer. Missing, conflicting, or outdated sources can still produce a poor result.
A question such as “How many products are in stock?” needs a different check. Matching a few passages cannot establish a total. For supported table imports, LoopReply can filter, sort, count, and aggregate the complete saved dataset. These operations depend on available rows, recognized columns, and suitable numeric values. Incomplete row coverage is rejected instead of being treated as a complete total.
Both kinds of answers use the data available to that Agent. A connected database supplies a saved query result; it does not give every chat message unrestricted access to your database.
1. Prepare a small, relevant source
Start with information you can verify: a current returns policy, a product catalogue, or a short FAQ. Remove duplicate versions and material the Agent should not share with visitors. Keep a copy of the expected answers for testing.
For a public support Agent, use public business information wherever possible. Private customer records require a separate access-control design. Attaching an order table does not establish which visitor is entitled to see each order.
The current upload formats are PDF, DOCX, XLSX, TXT, Markdown, CSV, and JSON. Convert an older .xls workbook to .xlsx or CSV before uploading. For web content, use the Websites tab rather than assuming an HTML file upload is supported.
| Source | Current technical limit |
|---|---|
| Uploaded file | 10 MB per file |
| CSV or XLSX | 10,000 data rows per file across its sheets, up to 150 columns |
| Database sync | 10,000 result rows and a 5 MB result-size limit |
Additional parsing limits can affect unusually complex files. Subscription allowances are separate; check your Workspace and current plans. A file with more than 10,000 data rows must be reduced or split. Do not assume a partial import represents the entire catalogue.
2. Upload documents and attach them to the Agent
- Open the correct Workspace and Agent, then Knowledge.
- In Files & Documents, choose Upload and select your files.
- Complete the upload step. Processing starts automatically, including if you close the upload dialog afterward.
- Check that processing completes successfully and the file has indexed chunks. An error or “Needs processing” state is not ready for answers.
- Confirm the file appears under Attached to Agent. Uploading from this page attempts attachment automatically. For an existing Workspace file, use Attach to Agent after it is ready.
The Workspace library and the Agent's attached files are different lists. A document being present in Your Files does not, by itself, establish that this Agent can use it.
Text-based PDFs are easier to check than scanned pages. The processor can attempt OCR when a PDF has no usable text layer, but recognition can fail or misread content. Test names, amounts, and dates against the original. Export complex tables as CSV or XLSX when you need reliable row-level checks.
If processing fails, read the displayed reason, fix the source where needed, and use Retry. Process handles a file that still needs indexing. A file left processing for more than ten minutes can show Restart processing; the server prevents a duplicate active job. These controls do not replace checking the final result.
3. Prepare CSV and XLSX data for exact questions
Use a clear header row, one record per row, and consistent units. Separate price from currency, and distinguish a product code from a numeric quantity. Avoid merged cells that obscure which value belongs to which record.
For example, a small product table might contain:
| product_code | name | price | currency | stock |
|---|---|---|---|---|
| 00123 | Small desk lamp | 29.50 | EUR | 8 |
| 00124 | Large desk lamp | 45.00 | EUR | 3 |
These are illustrative records, not live inventory. Store codes as text to preserve leading zeros. Use unambiguous numeric values in CSV, such as 29.50, rather than combining a currency symbol and locale-specific separators in the amount field. For XLSX, keep amounts in numeric cells and review their displayed values.
The workbook parser processes nonempty sheets within the file limits. Remove any sheet that should not become Agent knowledge. After upload, review the detected sheets, columns, and row counts; add column descriptions when a field needs explanation.
Then ask questions with answers you can check independently:
- “What is the price of product 00123?” should identify the right row and currency.
- “How many product rows are in this dataset?” should match the complete saved row count.
- “What is the total stock across all rows?” should match your spreadsheet calculation.
- “Find product 00999” should report a missing item if that code is absent.
Keep currencies and units separate when testing sums or averages. A total across EUR and USD prices would not be a meaningful price total. Our four-question spreadsheet checklist includes a repeatable synthetic example with 80 rows and an expected sum of 3,240.
4. Add selected website pages
- Open Knowledge → Websites → Add Website.
- Enter the website address and choose Discover Pages.
- Review the discovered pages and select the ones the Agent should use. You can also add a page from the same website manually.
- Choose Add & Start Crawling.
- Wait for the crawl to finish and inspect any reported error before testing answers.
Start with a small set of useful pages, such as product information, delivery terms, and help articles. Discovery checks the sitemap and follows links; it is not a promise to capture every page on a large site. The current interface supports up to three websites and discovers up to 50 pages per website.
Only accessible text can become useful knowledge. A login screen, blocked request, or page whose useful content does not appear in the fetched text may need a document export instead. Do not assume that a successful page request captured an entire interactive application.
Use Recrawl website when the source changes, then test a changed fact in a fresh conversation. A previously crawled page is a saved copy, not a live view of every website update.
5. Connect PostgreSQL or MySQL
LoopReply's database source supports PostgreSQL and MySQL. Use a dedicated account with read-only access to just the relevant tables or views. Restrict the query to information the Agent is allowed to reference.
- Open Knowledge → Data Sources → Add Data Source, then choose Database.
- Enter a name, database type, host, port, database name, username, and password.
- Add a supported
SELECTquery and choose a Sync Interval. - Use Test & Continue and review Data Preview. Check column names, sample values, and any limit warning.
- Choose Create Data Source, then wait for synchronization. Use Sync now when you need to request a fresh import.
A query for an example product table could be:
SELECT product_code, product_name, price, currency, stock
FROM products
WHERE active = true
Adapt table and column names to your database. If the result exceeds the limit, narrow it to the intended catalogue. Adding an arbitrary LIMIT changes what the Agent knows: a count of that saved subset is not a count of the whole database.
The connection form uses verified TLS and accepts an optional trusted CA certificate supplied by your database provider. Local and private network destinations are rejected. The connector also uses read-only transactions and bounds query duration and result size. These controls complement the database user's restricted permissions; they do not replace them.
The preview shows sample rows, not proof that synchronization completed. Check the source status and any error afterward. A failed refresh must not be interpreted as current data or as an empty catalogue. A successful query returning zero rows is a different result and should remove the old snapshot from current answers.
Scheduled synchronization applies to connected Data Sources. Uploaded documents do not automatically change when you edit a local file, and website recrawling is a separate action. Even with a short sync interval, answers are based on the last usable import rather than guaranteed real-time stock or pricing.
6. Test retrieval and the actual conversation
In Knowledge → Settings, use Test Knowledge to ask a question and inspect matching passages. Compare their content with the source document. The displayed match score describes retrieval similarity; it is not a measured probability that the final answer is correct.
Next, open Studio and test the draft conversation. You can ask the Architect to adjust the Agent's instructions, then inspect the saved settings and workflow alongside the preview. A useful instruction might be:
Answer product and policy questions using this Agent's available knowledge. If a requested fact is missing, say what is missing and offer human help. Preserve product codes and currencies. Use the saved dataset for counts and totals.
Treat that instruction as something to test, not a guarantee. Include a known answer, an unknown product or policy, an unrelated request, a table calculation, and a recently changed value. Decide the expected response for each before judging the generated reply.
In the workflow's AI Response step, review Knowledge Sources. All uses the sources attached to the Agent; Selected restricts the source set; None disables knowledge search for that step. A separate Knowledge Search node is available for explicit retrieval workflows, but it is not required for every AI Response configuration.
Instructions, appearance, and workflow edits in Studio remain drafts until Publish. Knowledge attachments and source changes are live settings, so they can affect an already published Agent without another publish. Use harmless test data or a separate test Agent while checking a new source. A workflow preview with external actions can contact the configured services.
After publishing configuration changes, repeat the key questions in the installed widget using a fresh conversation. Existing conversation history can contain an older answer, which makes it a poor freshness check.
Keep the knowledge current
Assign someone to review sources when products, prices, or policies change. Replace outdated uploads, recrawl changed website pages, and check connected-source sync status. Remove conflicting versions rather than relying on the Agent to decide which policy is authoritative.
Detaching a Workspace file from one Agent and deleting it from the library have different scopes. Review the action before using it, particularly when other Agents share that file. Neither action rewrites an answer already stored in a conversation.
For an incorrect answer, check these in order:
- Is the correct information actually in the source?
- Did processing or synchronization succeed?
- Is the source attached to the intended Agent and included in that workflow step?
- Does Test Knowledge return useful passages, or does a table query have the expected complete dataset?
- Do the current instructions and published workflow handle missing information appropriately?
Keep a short list of questions and expected answers and repeat it after source or configuration changes. Escalate unresolved questions through your human support process; requesting handover does not guarantee that an operator is online.
Common questions
Do I need to choose an embedding model?
There is no embedding-model selection step in this walkthrough. The current Agent Knowledge interface handles processing without asking you to select an embedding model. Focus on source quality, successful indexing, attachment, and tested answers.
How long does processing take?
It depends on source size, parsing complexity, OCR, and service availability. Use the processing status and error details rather than a fixed time estimate. Do not present newly uploaded content as ready before processing succeeds.
Can I use private or sensitive data?
Review the privacy policy and your access requirements before importing it. Limit the source to information the intended visitors may receive. This tutorial does not establish a security certification or suitability for regulated records; discuss specific requirements with the team.
What should I do first?
Start with one current source and a handful of questions whose answers you know. Confirm processing, attachment, retrieval, the draft response, and the published result. Then add more sources as real conversations reveal gaps. The knowledge base overview and current product facts explain how the pieces fit together.
Use a fixed source before testing your own catalog
Start with the downloadable CSV and XLSX fixture. Its known counts, total, and text identifier make parsing errors easier to distinguish from an answer-generation problem. The downloadable result file records parser checks, not an end-to-end live AI benchmark.
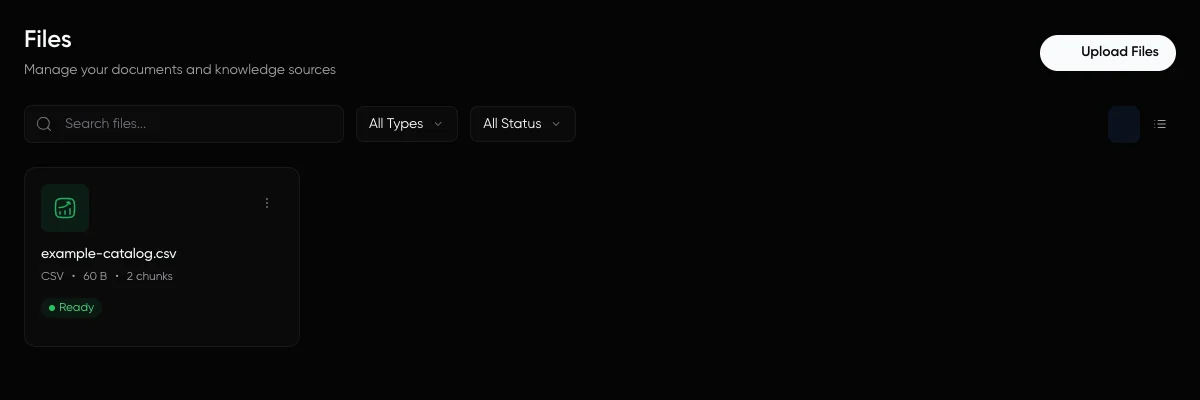
This actual Files interface shows Ready with illustrative data. The file must also be attached to the intended Agent. For a database pilot, expose only a small approved read-only result and compare the last synced rows with your reference query. Do not put account passwords or private customer tables into a public support Agent.
Then test a document-backed policy question and a question absent from every attached source. Use the missing-knowledge guide and failure diagnosis to record what needs correction.